AI-Based Automatic Code Generation for Parallel Confidential Computing
Please see the project website.Power Management in High Performance Computing Systems
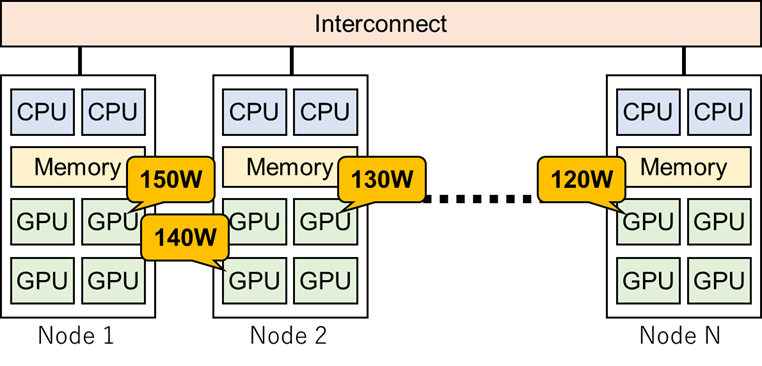
The future supercomputers are required for exascale computing power within 30 MW power constraints. For this purpose, we need to improve the power efficiency of various hardware components such as CPUs, GPUs, memories, and interconnects. Semiconductor chips such as CPUs and GPUs in the same SKU (Stock Keeping Unit) have power variation, which originates in manufacturing variability, and this feature helps to improve the energy efficiency of supercomputers. We assess the power variation on both CPUs and GPUs in various production systems and develop variation-aware job scheduling systems. This study is collaborated with RIKEN R-CCS.
Selected Publications
- K. Yoshida, H. Yamaki, H. Honda, K. Sato, and S. Miwa, Combining System- and User-Level Approaches to Improving Energy Efficiency in GPU-Based Supercomputers, The International Conference on High Performance Computing in Asia-Pacific Region (HPCASIA'26) Workshops, pp. 22-30 (2026)
- K. Yoshida, R. Sakamoto, K. Sato, A. Bhatele, H. Yamaki, H. Honda, and S. Miwa, VAHRM: Variation-Aware Resource Management in Heterogeneous Supercomputing Systems, IEEE Transactions on Parallel and Distributed Systems, Vol. 36, Issue 8, pp.1713-1727 (2025).
- K. Yoshida, S. Miwa, H. Yamaki, and H. Honda, Analyzing the Impact of CUDA Versions on GPU Applications, Parallel Computing, Vol.120, No.103081, 10 pages, Elsevier (2024).
- T. Kusaba, Y. Awaki, K. Yoshida, S. Miwa, H. Yamaki, T. Hanawa, and H. Honda, Power-Efficiency Variation on A64FX Supercomputers and its Application to System Operation, 2024 IEEE International Conference on Cluster Computing Workshops (CLUSTER Workshops), pp. 55-65 (Sep 2024).
- K. Yoshida, R. Sageyama, S. Miwa, H. Yamaki, and H. Honda, Analyzing Performance and Power-Efficiency Variations among NVIDIA GPUs, The 51st International Conference on Parallel Processing (ICPP), No. 65, pp.1-12 (acceptance rate: 84/311=27%).
Processor Architecture with Next-Generation Semiconductor Devices
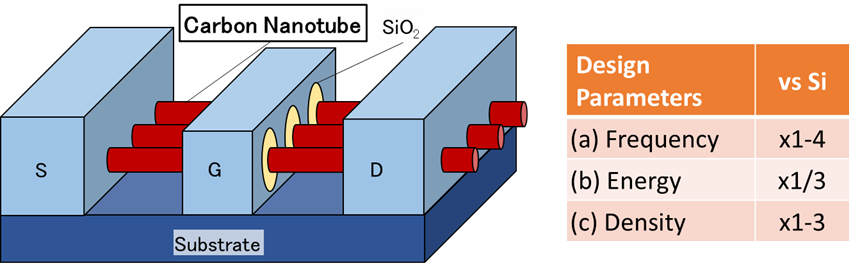
Modern processors are manufactured with silicon transistors and improve their performance as silicon transistors scale down; however, silicon transistor scaling is approaching the limit. Carbon nanotube transistors, which use nanometer-order carbon nanotubes as transistor channels, are considered a promising alternative to silicon transistors, and we, therefore, develop various design tools and architectures for processors manufactured with carbon nanotube transistors. We collaborate on this project with the University of Tokyo, Nagoya University, and Kyushu University.
Selected Publications
- S. Miwa, E. Sekikawa, T. Yang, R. Shioya, H. Yamaki, and H. Honda, CACTI-CNFET: an Analytical Tool for Timing, Power, and Area of SRAMs with Carbon Nanotube Field Effect Transistors, The 30th Asia and South Pacific Design Automation Conference (ASP-DAC), pp. 1350-1356 (2025) (acceptance rate: 168/587=29%)
- C. Shi, T. Koizumi, R. Shioya, H. Yamaki, H. Honda, and S. Miwa, MOOPSE: Leveraging High-Radix Booth Encoders for Area-Efficient Matrix Multiply Operations, 2025 62nd ACM/EDAC/IEEE Design Automation Conference (DAC), Work-in-Progress Session (poster presentation) (2025)
- C. Shi, S. Miwa, T. Yang, R. Shioya, H. Yamaki, and H. Honda, CNFET-OCL: Open-source Cell Libraries for Advanced CNFET Technologies, IEEE Access, Vol.12, pp. 165335-165347 (2024).
- C. Shi, S. Miwa, T. Yang, R. Shioya, H. Yamaki, and H. Honda, Analysis of 64-bit Parallel Prefix Adders and 32-bit Matrix Multiply Units Designed with 7-nm CNFET, 2024 61st ACM/EDAC/IEEE Design Automation Conference (DAC), Work-in-Progress Session (poster presentation) (Jun 2024).
- C. Shi, S. Miwa, T. Yang, R. Shioya, H. Yamaki, and H. Honda, CNFET7: An Open Source Cell Library for 7-nm CNFET Technology, The 28th Asia and South Pacific Design Automation Conference (ASP-DAC), pp.763-768 (acceptance rate: 102/328=31%).
System Software Development for TEE-Based Parallel Computing
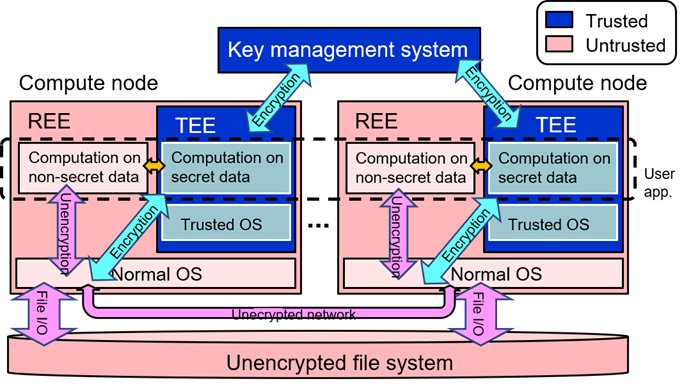
To serve as the ICT infrastructure supporting Society 5.0, there is a need for computer systems that deliver unprecedented levels of security and high performance. In this context, we are studying parallel computing systems using TEE (Trusted Execution Environment). Specifically, we are developing technologies such as MPI libraries for high-speed, secure data communication between TEEs and encrypted file systems designed for TEEs. This research is being conducted in collaboration with RIKEN R-CCS.
Selected Publications
- K. Shimojima, H. Yamaki, H. Honda, S. Matsuo, A. Takefusa, and S. Miwa, MPI-SGX: Enabling Confidential Computing for MPI Parallel Applications with Intel SGX Technology, The International Conference for High Performance Computing, Networking, Storage and Analysis (SC25, poster presentation) (2025) (Best Poster Candidate)
- K. Shimojima, S. Miwa, H. Yamaki, and H. Honda, Evaluating MPI Performance on SGX and Gramine, 2024 IEEE International Conference on Cluster Computing Workshops (CLUSTER Workshops) (poster presentation), pp. 172-173 (Sep 2024)
- S. Miwa, and S. Matsuo, Analyzing the Performance Impact of HPC Workloads with Gramine+SGX on 3rd Generation Xeon Scalable Processors, The SC'23 Workshops of the International Conference on High Performance Computing, Network, Storage, and Analysis (SC-W'23), pp. 1850-1858 (Nov 2023).